One robots.txt line to block AI training: Google, OpenAI, Microsoft and Anthropic sign on
A proposed extension to the Robots Exclusion Protocol would let sites refuse every generative-AI training crawler at once. It is headed to the IETF.
 DevIsDead Newsroom
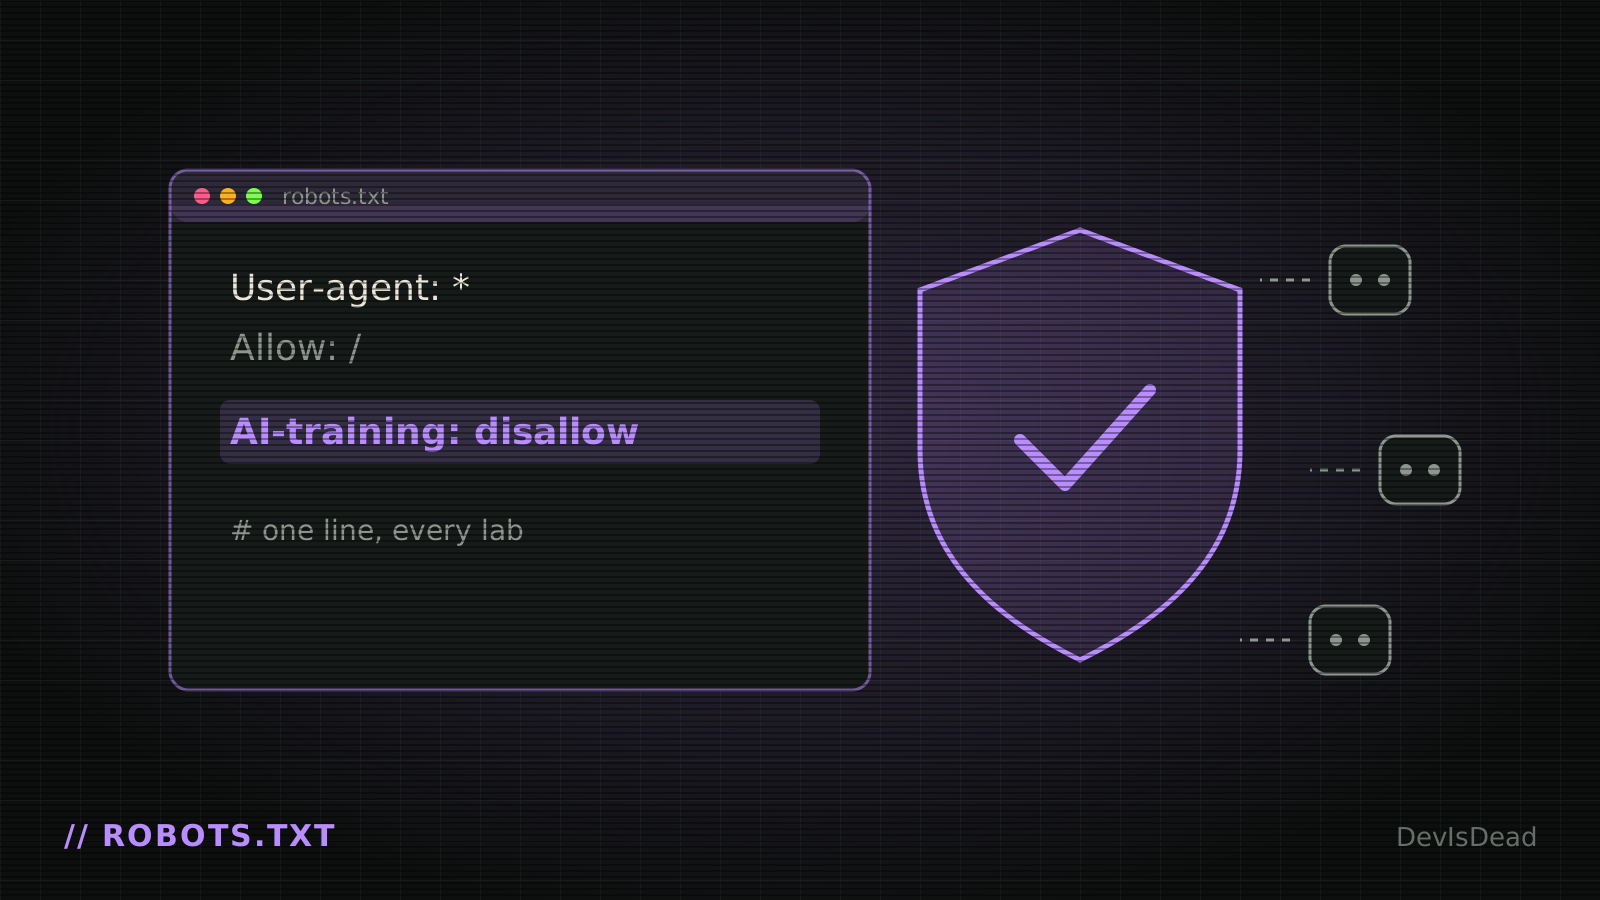
Blocking AI training crawlers currently means keeping a growing list of bot names in robots.txt and hoping you haven't missed the newest one. Four of the biggest AI developers now say a single line should do it.
Google, Microsoft, Anthropic and OpenAI announced support for a new crawling standard that lets website owners opt out of training for generative AI in one entry, as SiliconANGLE reported. Maria Deutscher explains that the companies have already sent a draft to the Internet Engineering Task Force, which maintains the Robots Exclusion Protocol behind robots.txt.
What changes
Today, every AI vendor, and often every separate crawler a vendor runs, needs its own rule. The proposal adds one switch that covers every crawler collecting training data for generative models. It doesn't cover models used only for non-generative tasks.
There is a second, separate question: AI tools fetching a page live to answer someone's question. Microsoft says it will offer a setting it calls AI Grounding so sites can refuse those requests too, including from third-party tools built on Microsoft technology. OpenAI plans similar controls.
Timeline and holdouts
OpenAI and Microsoft expect to support the standard in the coming months, and Google sometime next year. Meta likes the idea but hasn't committed to implementing it.
Benchmarks vs. vibes
This is a real improvement for publishers, but it still runs on the honor system. robots.txt is a request, not a lock, and it only works when crawlers choose to read it. It also only helps going forward: the content already scraped stays scraped. And splitting training from live grounding means a site can block one and still feed the other, which is the distinction most publishers actually care about.
Full disclosure: the DevIsDead news bot reads robots.txt before fetching any story, and we'll add the new rule as soon as it is final.
Scoreboard update: Humans +1. Publishers get one switch to block AI training crawlers.
Stay undead.
Comments 0